Our SciPy paper is out
ArcadeDB in Python: An In-Process Multi-Model Database is in the SciPy Proceedings. The research page has the method, the benchmark tables and the BibTeX entry.
What it covers
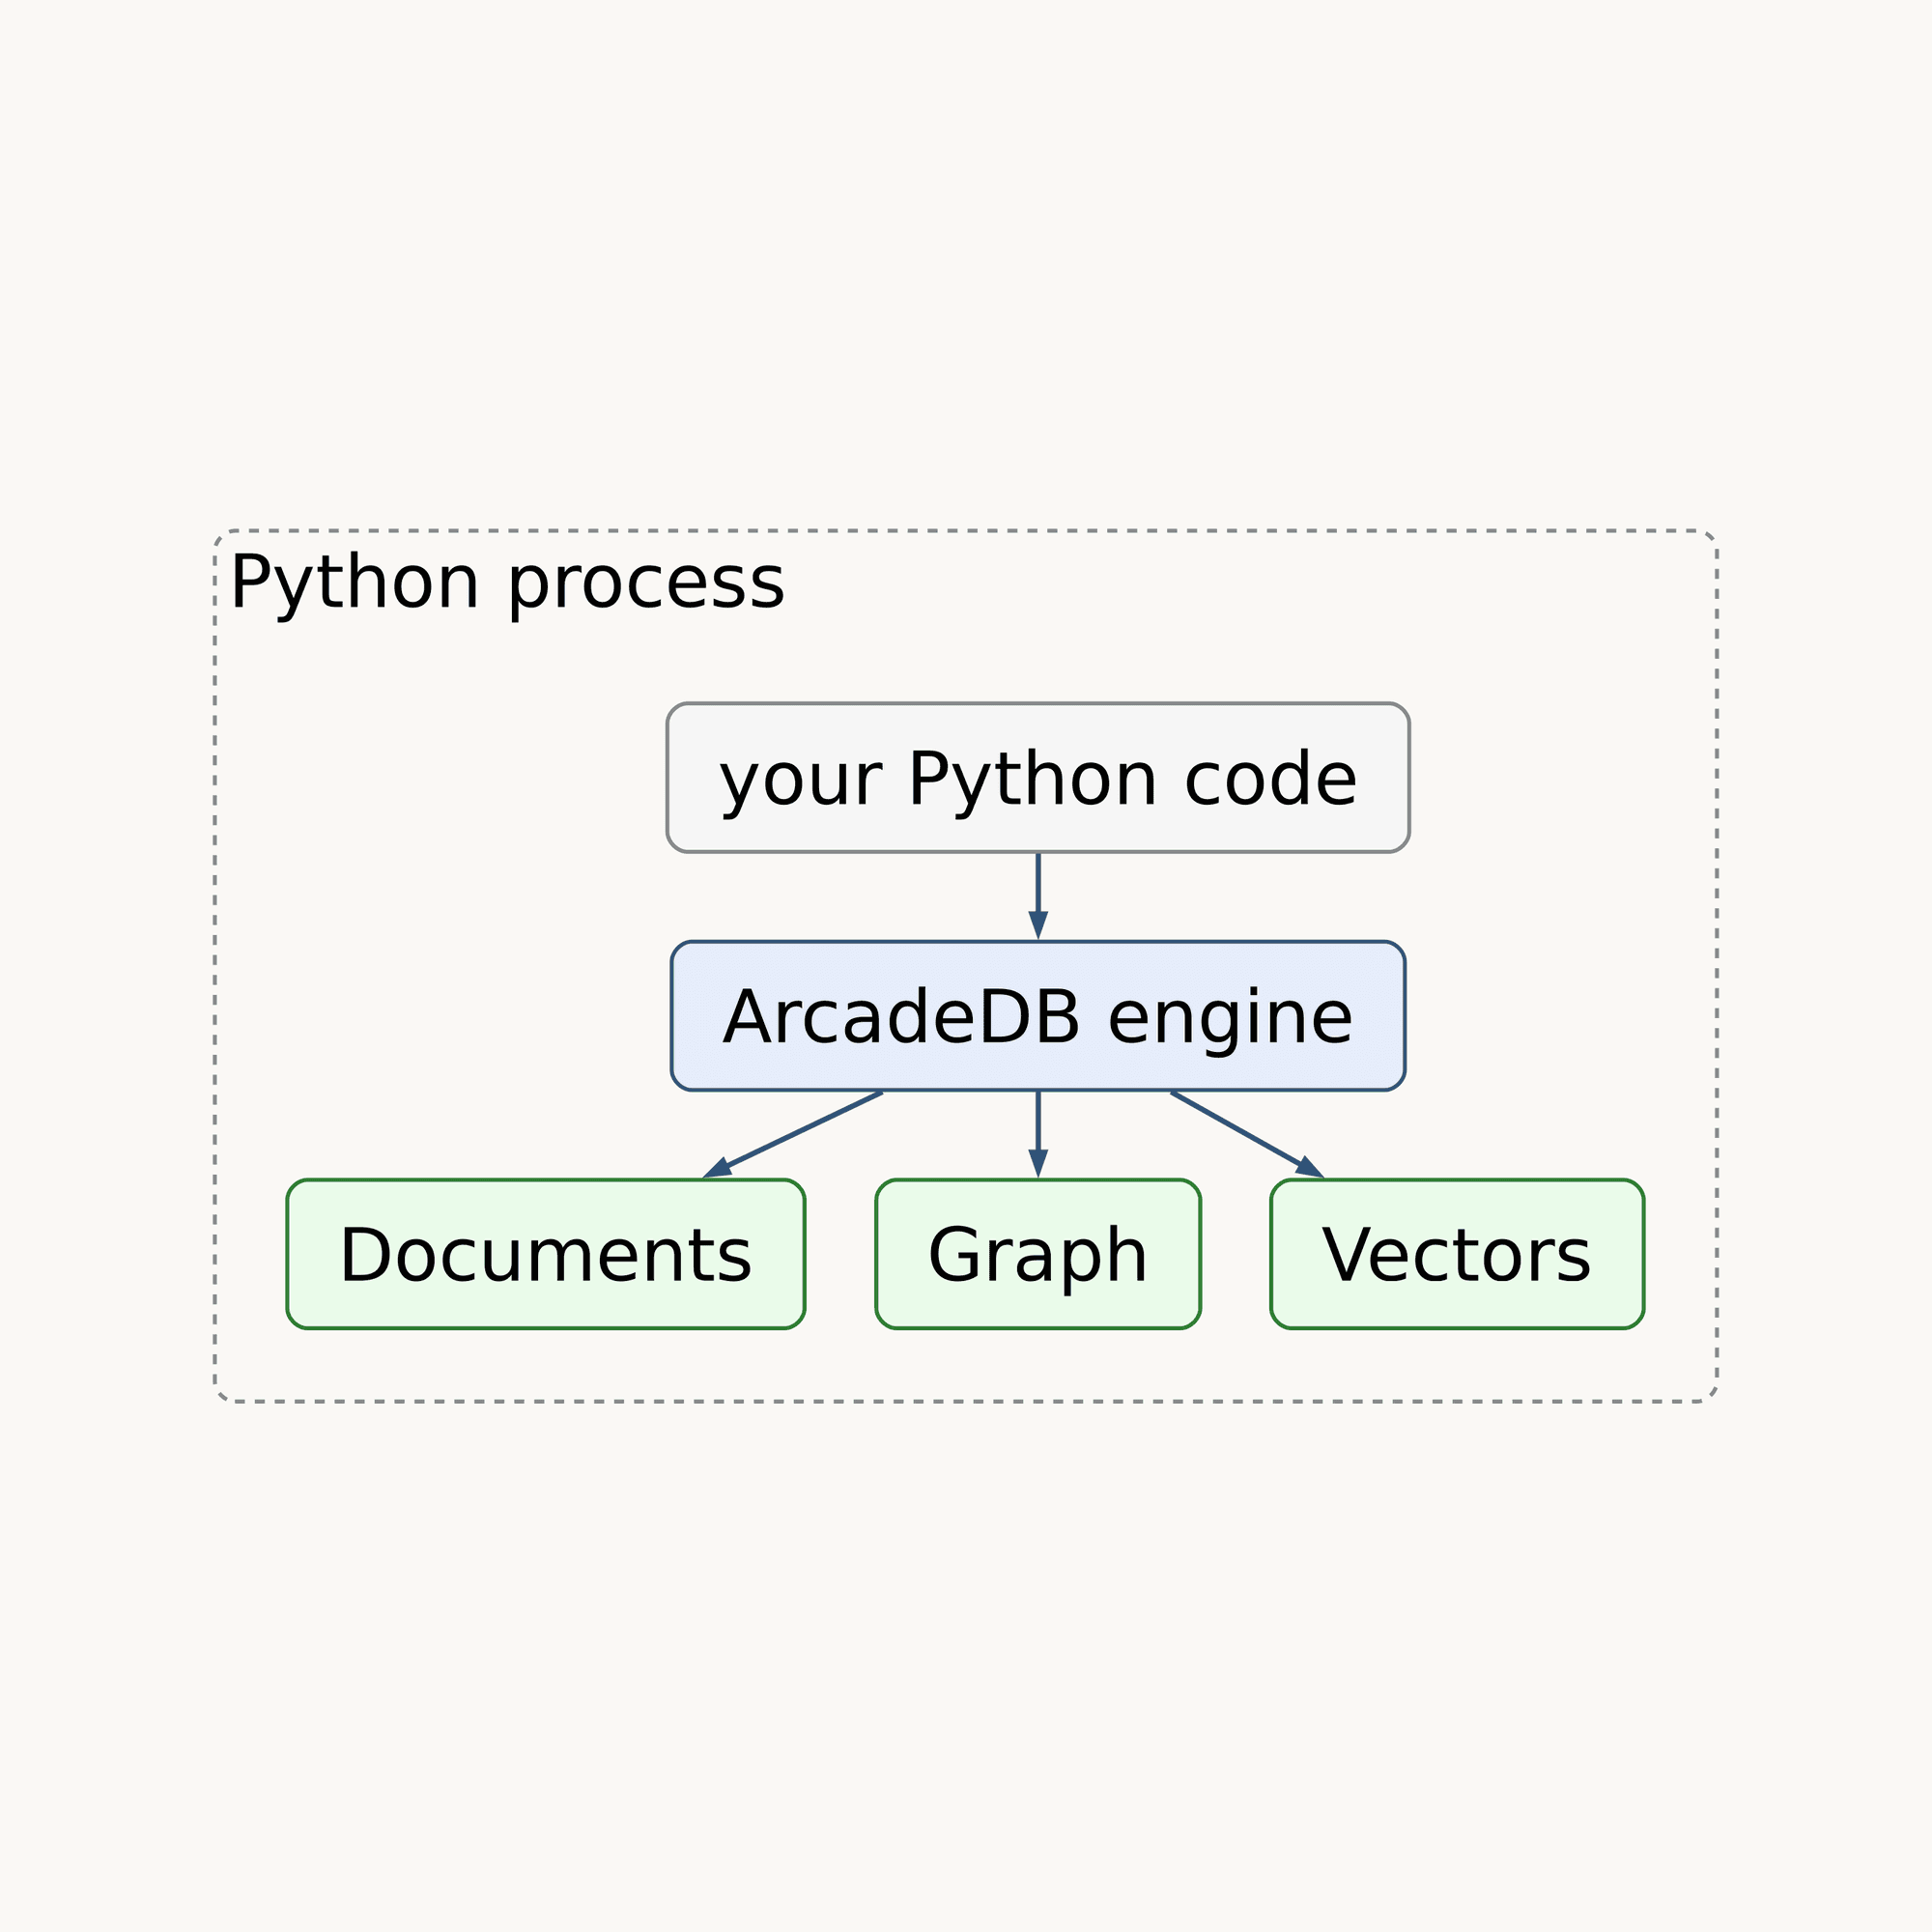
Some Python programs need transactions over documents, graph traversals and vector search at once. Usually that means three systems, each with its own copy of the data, and application code to keep the copies in sync.
The package runs ArcadeDB inside the Python process instead, so one database does all three. You query documents with SQL, the graph with openCypher, and vectors through an HNSW-family index. There are two builds with the same API: arcadedb, the native build, needs no Java, and arcadedb-jvm bundles a Java runtime. The paper measures the arcadedb-jvm build.
We show a workflow that chains a vector search, a SQL filter and a graph traversal over one dataset. We also benchmark the package against SQLite, DuckDB, LadybugDB and Chroma on a Q&A corpus. Each specialist wins on its own model. ArcadeDB is competitive on all three, and the cost is memory and loading time.
Resources